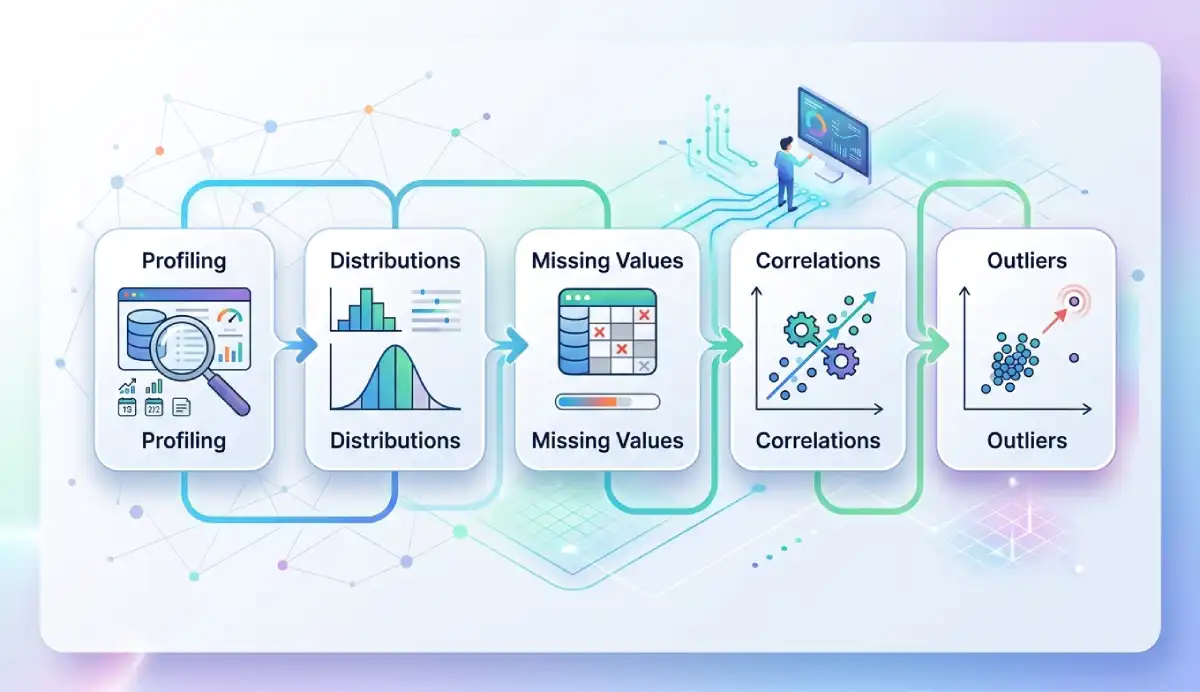
You open a spreadsheet with 25,000 rows. Before trusting its charts or calculating a correlation, you need to know what those rows mean. Are customer IDs repeated? Are dates genuine dates? Are missing values concentrated in one group? Does an average conceal a long tail?
Exploratory data analysis (EDA) is how you investigate those questions. It is a disciplined way of getting acquainted with a dataset before making strong claims about it.
What Is Exploratory Data Analysis (EDA)?
Exploratory data analysis (EDA) is the process of examining a dataset with descriptive statistics, quality checks, and visualizations to understand its structure, spot unusual values, explore relationships, and identify questions worth investigating. It is usually iterative: discoveries lead to additional checks, not immediately to firm conclusions.
EDA stands for Exploratory Data Analysis. The approach was popularized by statistician John W. Tukey, including through his 1977 book Exploratory Data Analysis. Its guiding idea is to let the observed data inform subsequent questions and methods rather than impose a model too early.
- DefinitionInvestigate the data before asserting conclusions
- FocusStructure, quality, distributions, relationships
- MethodsCounts, summaries, plots, cross-tabs, comparisons
- OutcomeDocumented findings and better next questions
- MindsetExplore → question → verify → revisit
Why Exploratory Data Analysis Matters
A single statistic rarely describes an entire dataset. Two sales datasets could have the same average order value but different numbers of tiny orders, refunds, and exceptionally expensive purchases. A correlation coefficient could be near zero even when a strong curved relationship is visible on a scatter plot.
EDA helps you catch misleading summaries before they become misleading reports. It can also reveal that the intended analysis is impossible without better data. If a file contains one row per order line, counting rows does not give the number of orders; if repeated visits belong to the same person, treating visits as independent people can misrepresent a survey.
EDA is useful in research, business reporting, quality control, statistics, and machine learning. It does not replace formal statistical inference or data cleaning. It tells you what deserves correction, closer analysis, or validation. For the broader workflow, see what data analysis is.
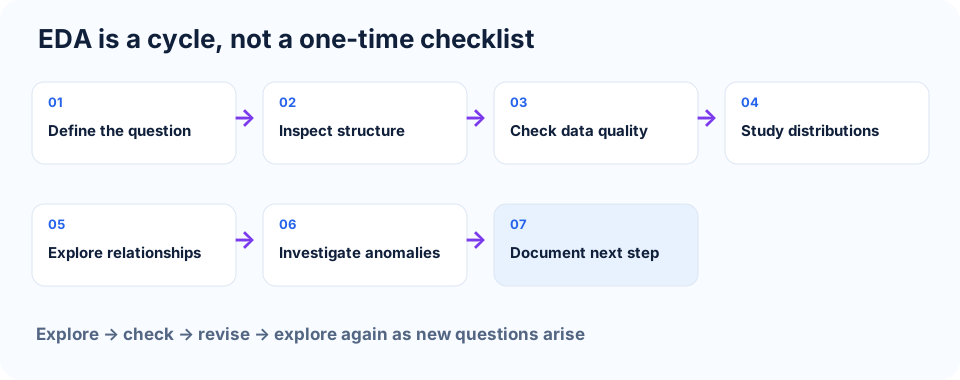
How to Perform Exploratory Data Analysis: 7 Steps
These seven stages are a practical guide, not a compulsory industry standard. A small survey may require fewer checks; longitudinal medical or operational data may need more. The important habit is to record what you examined and why.
Step 1: Define the question and unit of observation
Start with what you want to learn. “Explore sales” is broad; “Why does the order-value distribution differ across acquisition channels?” gives a direction. Then establish what one row represents: one customer, one order, one order item, one survey response, or one day. This controls how counts and summaries should be interpreted.
Record variable definitions, units, the collection period, and the expected unique identifier in a small data dictionary. An order ID can look numeric, but its digits are an identifier rather than a quantity to average. Output: an analysis question, row definition, key fields, and known limitations.
Step 2: Inspect structure, data types, and identifiers
Count rows and columns; read a sample of records; review column names, dates, and plausible ranges. Separate quantitative measurements from categories, dates, text, identifiers, and ordinal responses. Find values imported as the wrong type: prices stored as text, dates interpreted in the wrong locale, or product codes with lost leading zeros.
Check whether keys are unique when uniqueness is expected. An identical customer name does not make two orders duplicates. A transaction may legitimately contain multiple lines with the same order number. Output: a type and structure inventory, with questions to resolve.
Step 3: Profile data quality and missing values
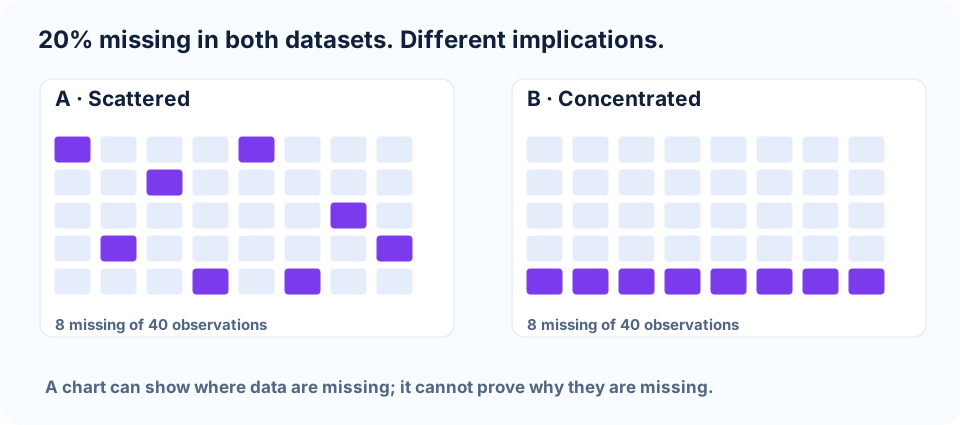
Count blanks, explicit placeholders, invalid dates, improbable values, inconsistent labels, and possible duplicates. For important fields, calculate both the number and percentage missing, but also inspect which records are missing. Are delivery times missing mostly for a particular courier or month? That pattern may change how useful those records are for an analysis.
Do not automatically replace blanks with zero, impute medians, or delete rows. A blank could mean unknown, not measured, or not applicable. EDA flags the problem; a defensible cleaning plan determines the action. See the Excel data-cleaning guide for a practical correction workflow. Output: a data-quality log and unresolved questions.
Step 4: Explore individual variables (univariate EDA)
For numbers, start with count, minimum, maximum, mean and median, quartiles, and standard deviation or interquartile range when appropriate. Then plot a histogram or box plot to inspect the shape. The same mean can conceal skew, long tails, isolated values, or more than one peak.
For categorical columns, count categories and calculate their proportions. Look for inconsistent spellings, rare levels, and suspicious codes. A histogram's peaks can change when you change bin widths; two peaks may suggest groups but do not prove distinct populations. Output: per-variable summaries with visual notes.
Step 5: Explore relationships (bivariate and multivariate EDA)
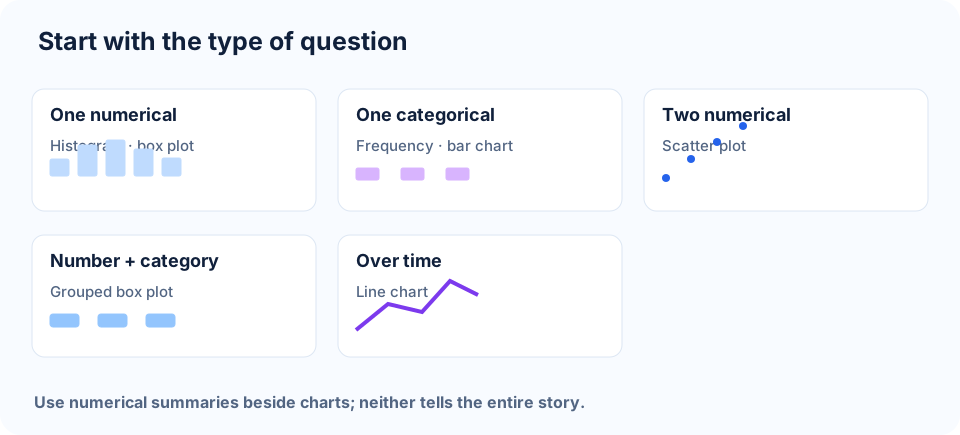
Pair methods with variable types. For two numerical variables, use a scatter plot and possibly a correlation coefficient. For a number compared across categories, use grouped summaries or side-by-side box plots. For two categorical variables, use a cross-tabulation with proportions and subgroup counts. For time-indexed data, plot values over time before pooling everything into one average.
Three or more variables call for additional care: a pooled relationship may disappear or reverse within groups. Pair plots, faceting, grouped tables, and correlation matrices are starting points, not complete explanations. Output: relationships to investigate, possible confounders, and charts with denominators.
Step 6: Investigate unusual observations and hidden structure
Flag impossible dates, unusually large values, sharp trend changes, unexpected clusters, and records beyond a box plot's fences. Cross-check original files and domain rules. An order of $4,800 might be a genuine wholesale purchase or an entry error; the distribution alone cannot decide which.
Compare results with the flagged records retained and, when justified, excluded or handled robustly. Document any changes and why you made them. Output: investigated anomalies, unresolved uncertainties, and sensitivity checks.
Step 7: Document findings and choose the next step
Write down what the data show, what you suspect, what is still uncertain, and which check comes next. The next action may be fixing a source-system problem, gathering more data, segmenting the analysis, choosing a statistical test, or validating a predictive model.
EDA is iterative. You may repeat several stages after correcting an import, adding new observations, or seeing unexpected model residuals. Output: a short report with reproducible definitions, charts, caveats, and a decision about next analysis.
Types of Exploratory Data Analysis
EDA is often described by the number of variables considered and by whether the technique is graphical. These are two overlapping ways to classify work, not competing methodologies.
Univariate
Inspect one variable: its distribution, range, center, spread, or category counts. Example: a histogram of order values.
Bivariate
Compare two variables: a scatter plot of items versus order value, or box plots of order value by sales channel.
Multivariate
Explore three or more variables together, including grouped relationships and possible confounding.
Graphical and numerical
Combine plots with summary statistics, frequency tables, quartiles, cross-tabs, and counts; neither is sufficient alone.
Use numerical summaries to quantify differences and visuals to see structures those summaries miss. EDA is not a contest to generate the most plots. Each table or chart should answer a question.
Which EDA Method Fits Each Variable Type?
| Data combination | First checks | Useful display |
|---|---|---|
| One numerical variable | Count, quartiles, mean, spread | Histogram, box plot |
| One categorical variable | Counts, proportions, unusual labels | Bar chart, frequency table |
| Numerical + numerical | Association, curvature, unusual pairs | Scatter plot, fitted curve as a guide |
| Numerical + categorical | Group sizes, centers, spreads | Grouped box plots, summary table |
| Categorical + categorical | Counts and within-group proportions | Cross-tab, grouped bars |
| Time-indexed observations | Trend, gaps, seasonality, order | Line chart, time-ordered plot |
A quick practical sequence is to start with tables, then choose a plot that reveals what the table cannot. For distributions, try AmriData's Histogram Maker; for quartiles and flagged extreme values, consider the Box Plot Maker (check both tools' current behavior before relying on results).
How to Explore Missing Data Without Guessing
Missingness can look simple in a spreadsheet and still distort results. Suppose an income field is missing for 423 of 8,000 responses. The missing percentage is 423 ÷ 8,000 × 100 = 5.2875%, about 5.29%. That percentage is useful to report, but it does not explain why answers are absent.
Compare missingness across dates, channels, locations, outcomes, and available demographics where appropriate. If a field is consistently absent from one data source, the source integration may be broken. If it is missing mainly for high-income respondents, replacing blanks with the overall median may bias comparisons.
| Label | Meaning | What EDA can do |
|---|---|---|
| MCAR | Missing completely at random: missingness does not depend on observed or unobserved values. | Check for evidence inconsistent with that assumption; cannot prove it from a chart. |
| MAR | Missing at random conditional on observed variables. | Inspect whether observed groups help explain which entries are missing. |
| MNAR | Missingness can depend on the unobserved value even after conditioning on observed information. | Consider domain knowledge and sensitivity analyses; mechanism cannot be read directly from blanks. |
Do not choose deletion or median filling from a percentage threshold alone. Even small amounts of systematically missing data can matter; simple imputation can reduce apparent variability or distort relationships. A missing-data plan should reflect the analysis goal and plausible assumptions.
Correlation in EDA: What a Coefficient Can and Cannot Tell You
Pearson's correlation coefficient, often written r, summarizes the direction and strength of a linear relationship between two numerical variables. Values range from −1 to +1 when defined. A positive value indicates an upward linear tendency; a negative value indicates a downward one. Values near zero indicate little linear association—not necessarily independence.
Consider five paired observations with x = −2, −1, 0, 1, 2 and y = 4, 1, 0, 1, 4. Here y equals x² exactly, yet Pearson's r equals 0 because the upward and downward parts balance in the linear calculation. The relationship is unmistakable on a U-shaped scatter plot.
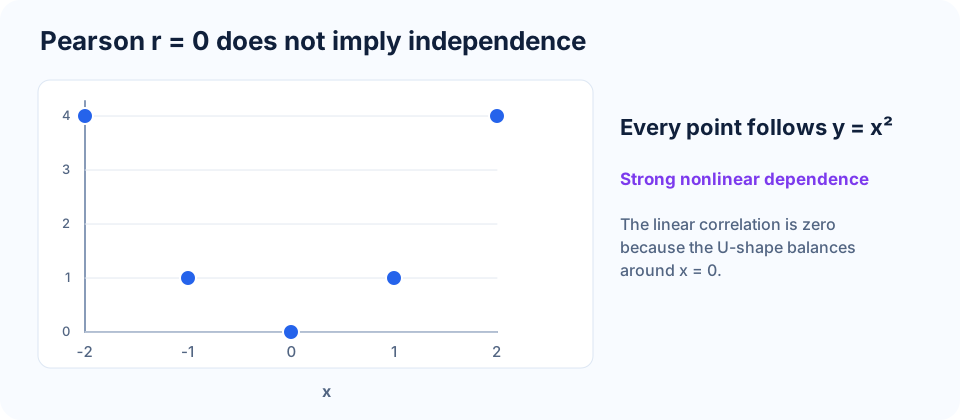
Always inspect the scatter plot, sample size, subgroup structure, and extreme observations before interpreting r. Correlation does not establish that changes in one variable cause changes in the other. An apparent relationship can arise through a third variable, selection effects, or chance exploration.
How to Investigate Outliers and Unusual Patterns
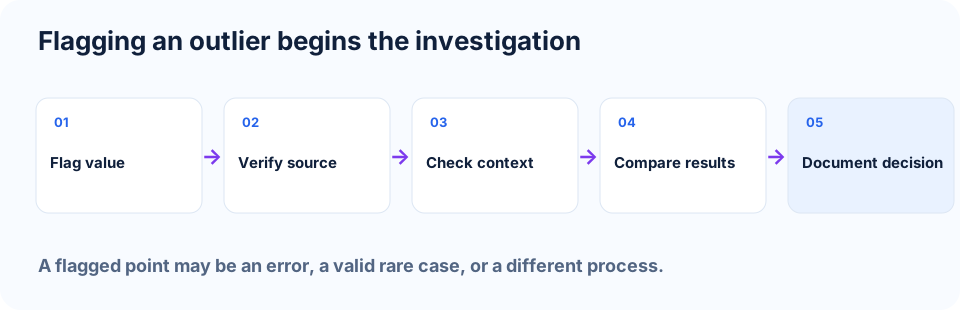
An outlier is an observation that appears unusual relative to a chosen reference. One common box-plot convention uses Tukey-style fences: lower fence = Q1 − 1.5 × IQR and upper fence = Q3 + 1.5 × IQR, where IQR = Q3 − Q1. Values beyond these fences are flagged for investigation; they are not automatically errors.
A surprising value could be a misplaced decimal, a refund represented as a sale, a legitimate wholesale order, or a different data-generating process. Inspect the source record, surrounding variables, units, and historical context before altering anything. Consider reporting the analysis both with and without a suspect record as a sensitivity check, but exclude it only when there is a defensible reason.
- Flag a record using a documented rule or domain threshold.
- Verify the entry against its source and check units.
- Investigate whether it belongs to the population being studied.
- Compare conclusions with robust summaries or sensitivity checks.
- Document the decision to correct, retain, flag, or exclude.
Also watch for unexpected gaps, two peaks, and patterns that appear only after separating dates or groups. A seemingly bimodal distribution may indicate multiple processes, but it can also be an artifact of binning, small samples, or noise.
Worked EDA Example: 5,000 Online Store Orders
Imagine a hypothetical store export containing 5,000 rows and nine columns: Order_ID, Date, Channel, Customer_Type, Order_Value, Items, Discount, Delivery_Days, and Returned. The example is invented for teaching; the values below are not AmriData customer results.
EXPORTED ROWS5,000One row is intended to represent one orderMISSING DELIVERY TIMES8383 ÷ 5,000 = 1.66% of export rowsPOSSIBLE DUPLICATES12Exact repeated rows to review, not yet deleteObservation 1: Structure and quality
Order_ID is expected to identify one order. The initial check finds 12 exact duplicate rows, four Order_Value cells stored as text, and Channel entries spelled Social, social, and SOCIAL. Those findings suggest technical cleanup may be needed, but the duplicate records still require a check against the store's actual order system.
The 83 missing delivery times equal 1.66% of the original 5,000 export rows. The number to report may change after reconciling duplicate orders; we would recalculate it rather than assume the initial denominator remains appropriate. Next check: group the missing times by courier, order date, and returned status.
Observation 2: Individual distributions
Suppose the summary for valid Order_Value observations gives a median of $58 and a mean of $74. That difference suggests inspecting the high-value tail; a histogram then shows a pronounced right tail. We do not infer its shape solely from the mean-median difference. The typical order is not necessarily described well by the mean in this scenario.
Observation 3: Relationships
A scatter plot compares Items with Order_Value. A grouped box plot compares Order_Value across Channel. A contingency table compares Returned by Customer_Type using both counts and within-group rates. These are useful descriptive questions, but no statistical significance or causal interpretation has been established.
Observation 4: The $4,800 order
One $4,800 order sits far above most transactions. It may be a valid bulk purchase. Checking its source transaction, quantity, product category, and currency is more informative than deleting it from the export. Report summaries with the record present, and—if justified—show a sensitivity comparison.
| Observation | Possible explanation | Next check |
|---|---|---|
| 12 identical export rows | Repeated export, or legitimate duplicate events | Compare order keys and source records |
| 83 delivery-time blanks | Courier feed issue or undelivered orders | Inspect blanks by courier/date/status |
| Mean $74; median $58 | High-value tail may pull the mean upward | Inspect histogram, quartiles and source values |
| One $4,800 order | Valid wholesale transaction or error | Check invoice, units, currency |
Supported conclusion: The export needs key validation, category normalization, and closer distribution review before the store uses it for a final report. We cannot conclude that social traffic caused larger purchases, that missing delivery times are harmless, or that the large order is wrong. This is what a useful EDA report looks like: what you know, what you suspect, and what you will verify.
Which Tools Can You Use for EDA?
You do not need Python to begin exploratory analysis. Excel or a comparable spreadsheet works well for smaller files: filters, PivotTables, count formulas, histograms, and scatter plots can reveal many important issues. SQL helps profile tables in databases. Python with pandas and plotting libraries, and R with data frames and graphics packages, become useful for repeatable or larger workflows.
| Tool | Useful for | Watch for |
|---|---|---|
| Excel | Small tables, manual review, PivotTables | Accidental edits, inconsistent formulas |
| SQL | Database counts, keys, missingness, grouped summaries | Join duplication, null handling |
| Python / R | Reusable profiling, plots, transformations | Hidden assumptions in code and defaults |
| AmriData | Explore datasets through available site features | Verify current feature outputs and definitions |
For a guided interface, see AmriData's Data Analysis feature page to check supported upload formats and current profiling options. Do not assume any platform can determine the correct meaning of duplicates, missingness, or outliers automatically.
EDA vs. Data Cleaning vs. Confirmatory Analysis
These activities overlap but answer different questions. EDA asks what the data contain and what deserves investigation. Data cleaning applies justified corrections to known quality issues. Confirmatory analysis evaluates specified questions using formal methods and suitable assumptions. EDA can continue after modeling when residuals or errors reveal a new problem.
| Activity | Main question | Typical result |
|---|---|---|
| EDA | What is happening in this dataset? | Patterns, issues, hypotheses, next checks |
| Data cleaning | Which known errors should be corrected, and how? | Validated transformations and change log |
| Confirmatory analysis | How strongly does evidence address a defined claim? | Estimates, uncertainty, tests or validation |
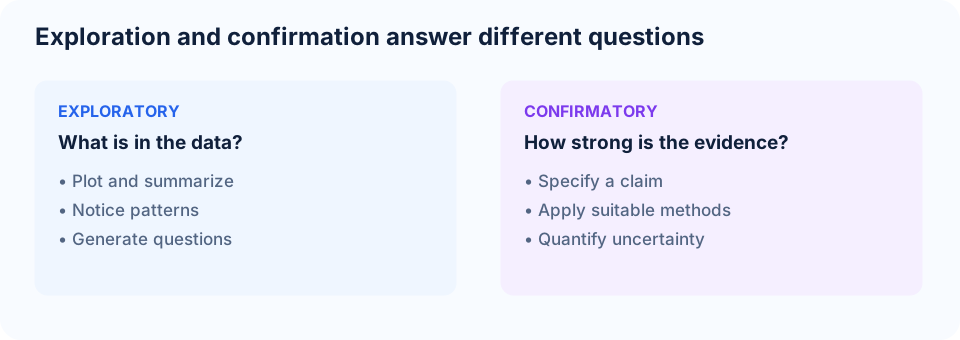
If you search hundreds of patterns and then test the most striking one on the same records as though it had been specified in advance, you can overstate the evidence. Stronger claims may need a prespecified analysis, held-out data, replication, or suitable adjustment for multiple comparisons.
Common EDA Mistakes to Avoid
- Skipping row definitions: Order items and orders are not interchangeable. Define the unit of observation first.
- Trusting one number: An average or Pearson r can conceal tails, subgroups, or nonlinear structure. Show the underlying data.
- Trusting one chart: Axis choices, histogram bins, and tiny groups can distort perception. Check counts and alternate views.
- Treating every odd value as an error: Flags require source checks and domain context.
- Using a missing-data percentage as a rule: Understand patterns and causes before deleting or filling.
- Forgetting time: Mixing months with distinct promotions or processes may conceal important changes.
- Presenting exploration as proof: An observed pattern is a hypothesis until adequately evaluated.
- Making undocumented changes: Preserve raw files, code or steps, and decisions so somebody else can reproduce the analysis.
Reusable EDA Checklist
Use this checklist each time you receive a new dataset. It is intentionally compact; expand the checks for higher-risk projects.
- ☐ Define the question, row unit, time period, and sources.
- ☐ Check dimensions, keys, variables, units, and inferred data types.
- ☐ Count duplicates, missing entries, invalid values, and unusual categories.
- ☐ Compare missingness and data quality across relevant groups.
- ☐ Summarize each numerical and categorical variable.
- ☐ View histograms, box plots, bar charts, and time plots as appropriate.
- ☐ Compare pairs and groups, checking nonlinear patterns and denominators.
- ☐ Investigate flagged values without automatic deletion.
- ☐ Separate observations, possible explanations, and next checks.
- ☐ Save a reproducible summary and decide what analysis follows.
Frequently Asked Questions About EDA
What does EDA stand for?
EDA stands for Exploratory Data Analysis, the process of understanding the structure, quality, variation, and relationships in a dataset before making strong analytical claims.
What are the seven steps of exploratory data analysis?
Define the question, inspect structure, check quality and missingness, study individual variables, explore relationships, investigate unusual observations, and document findings and next actions. It is a useful framework, not a universal mandatory sequence.
What is the difference between univariate, bivariate and multivariate EDA?
Univariate EDA examines one variable, bivariate EDA examines two together, and multivariate EDA explores three or more variables. Each can use numerical summaries and graphics.
Can you perform exploratory data analysis in Excel?
Yes. For many tabular problems Excel offers sorting, filters, PivotTables, summary formulas, histograms, and scatter plots. More repeatable workflows may benefit from Power Query, SQL, Python, or R.
Does a Pearson correlation of zero mean independence?
No. A Pearson correlation of zero means no linear correlation in the data being summarized. Strong nonlinear dependence can still exist; inspect a scatter plot.
Should I fill all missing numerical values with the median?
No. The appropriate approach depends on why data are missing, the analysis goal, and other variables. Simple median imputation can distort variability and associations.
Does an IQR outlier flag mean a value is wrong?
No. The 1.5×IQR fence is a common way to flag observations for review. An unusual value may be valid and important; verify before changing or removing it.
Does EDA prove a causal relationship?
No. EDA can reveal associations and generate hypotheses. Causal claims require suitable study design, assumptions, and analysis beyond exploration alone.
How is EDA different from descriptive statistics?
Descriptive statistics summarize characteristics such as center, spread, and frequency. EDA uses those summaries alongside charts, quality checks, context, and follow-up questions in an iterative investigation.
When is exploratory data analysis finished?
When the dataset's key properties and limitations are understood well enough to make the next analytical decision. You may return to EDA after cleaning, modeling, or receiving new data.
Key Takeaways
Good exploratory data analysis is less about producing a dashboard and more about asking better questions of a dataset. Start by understanding rows, columns, and context. Combine numerical summaries with visual checks. Treat missing data, correlations, bimodality, and unusual values carefully. Record what you observed separately from what you still need to verify.
For the statistical rationale behind exploratory graphics and assumptions, consult the NIST/SEMATECH guide to EDA. For an introduction to wider methods, see the AmriData data analysis guide.