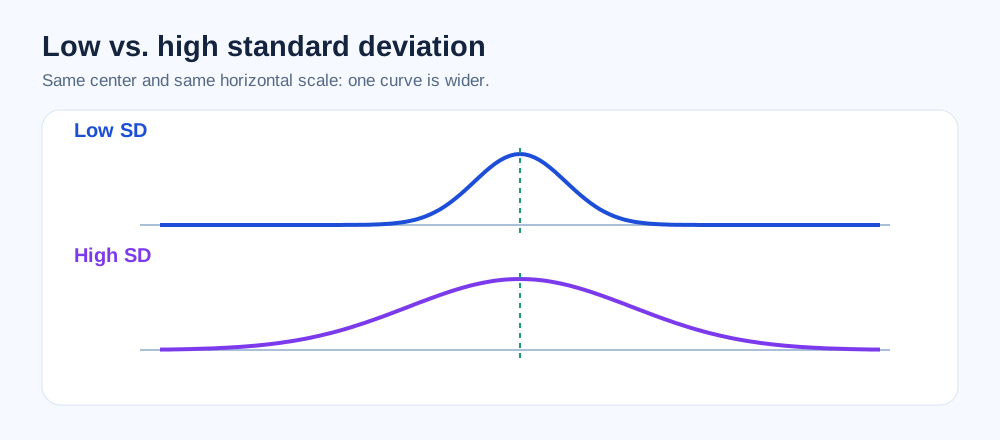
Standard deviation measures how spread out numerical values are around their mean. A low standard deviation indicates observations tend to cluster near the mean; a high standard deviation indicates they vary more widely. Population standard deviation is denoted by σ (sigma) and the usual sample standard deviation by s. It describes variability, not whether that variability is automatically good or bad.
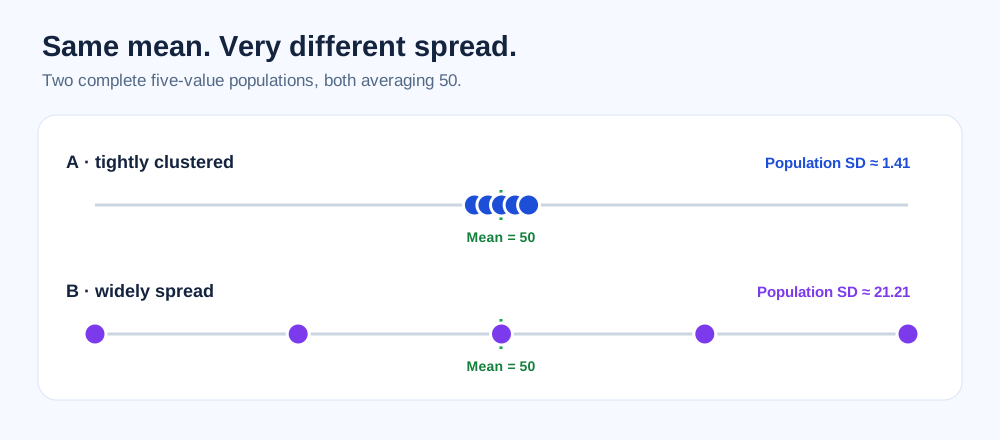
Imagine two classes with the same average score of 50. Their scores could still be almost identical or spread from 20 to 80. The mean tells you the center; the standard deviation helps describe the differences around it. For a review of the center itself, see mean, median and mode.
Standard Deviation at a Glance
- Measures Spread of numerical observations around their mean
- Population symbol σ (sigma); divides by N
- Sample symbol s; usually divides by n − 1
- Units Same units as the observations
- Relationship Standard deviation = square root of variance
- Important limit SD alone cannot reveal skew, tails or outliers
Why Does Standard Deviation Matter?
A mean summarizes location, but it cannot tell you how consistent, variable, or dispersed the observations are. For instance, two services might each average a delivery time of three days: one regularly delivers in about three days, while the other alternates between same-day and week-long delivery. Understanding spread changes how you plan resources and communicate expectations.
Standard deviation helps describe variation in exam scores, delivery times, manufacturing measurements, scientific experiments and financial returns. It uses every observation and is valuable in statistical models. But the result should be read beside the data units and distribution shape; a high SD is not necessarily a flaw, and a low SD is not necessarily a success.
What Does Standard Deviation Actually Measure?
Each observation has a deviation from the mean: value − mean. Deviations below the mean are negative; deviations above it are positive. The signed deviations add to zero, so directly averaging them would tell us nothing about the spread. Instead, the usual formula squares the deviations, combines those squares, and takes a square root.
Squaring prevents positives and negatives from canceling and gives larger differences more influence. The square root then returns the statistic to the original measurement units. Technically, population SD is a root-mean-square deviation from the population mean—not the ordinary average of absolute distances. You can think of it as a characteristic distance from the mean without treating it as a literal average distance.
Standard Deviation Formula: Population and Sample
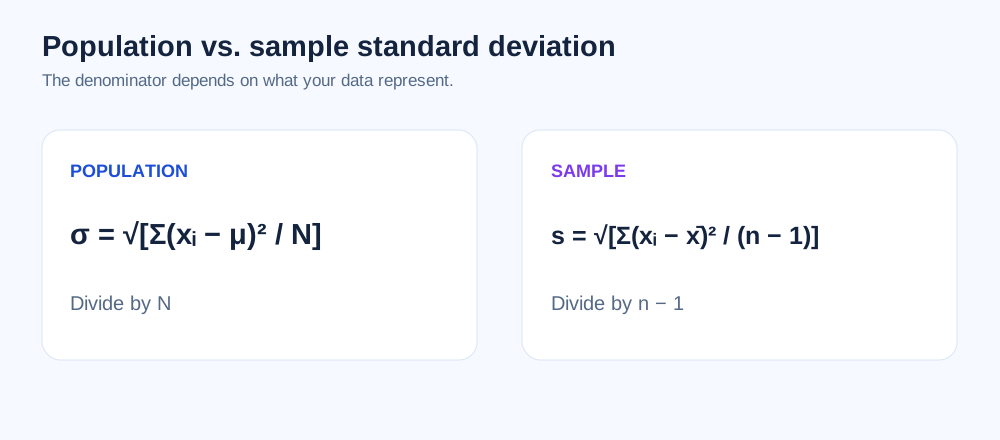
The formula depends on the role of the observations. Use the population formula when the values represent the complete population you want to describe; use the usual sample formula when the observations are treated as a sample used to estimate variability in a larger population.
Population standard deviation formula
σ = √[Σ(xᵢ − μ)² / N]
σ is population SD; xᵢ is an individual value; μ is the population mean; N is the population size; and Σ means add all terms.
Sample standard deviation formula
s = √[Σ(xᵢ − x̄)² / (n − 1)]
s is sample SD; x̄ is sample mean; and n is the sample size. Under the usual independent sampling assumptions, dividing squared deviations by n − 1 rather than n corrects for using the sample mean to estimate an unknown population mean. This is Bessel's correction for sample variance; it does not make the sample SD exactly unbiased.
| Feature | Population SD | Usual sample SD |
|---|---|---|
| Symbol | σ | s |
| Center used | Population mean μ | Sample mean x̄ |
| Denominator | N | n − 1 |
| Variance | σ² | s² |
| Typical question | How dispersed is the complete group? | What is variability in a larger population? |
Why Does Sample Standard Deviation Use n − 1?
When we calculate a sample mean from the observations themselves, the deviations around that mean are constrained: they must sum to zero. Once n − 1 deviations are known, the last one is determined. This is the intuition behind n − 1 degrees of freedom.
In ordinary random sampling from a population with finite variance, using n − 1 makes sample variance an unbiased estimator of population variance. Taking its square root gives the familiar sample SD, which is generally not perfectly unbiased. If the dataset is the entire population of interest, the population divisor N may be appropriate even when that group is small. Also, the usual sample SD requires at least two observations.
How to Calculate Standard Deviation Step by Step
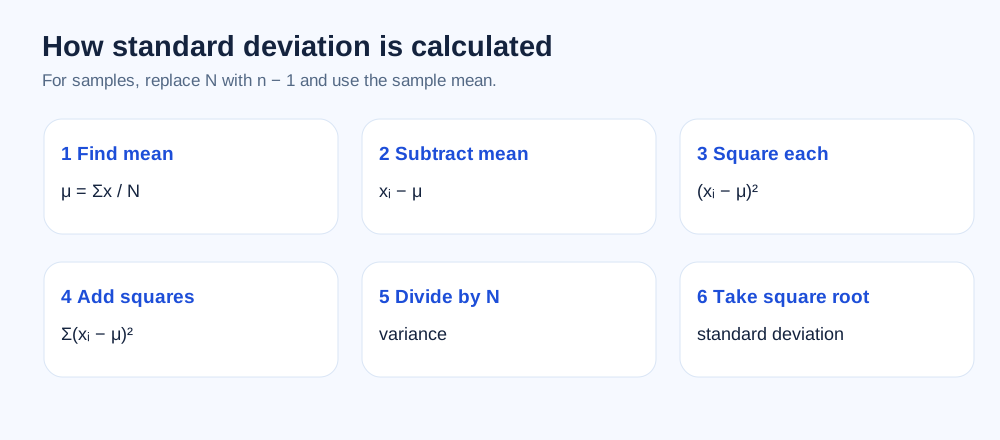
- Find the mean. Add the values and divide by the number of observations.
- Subtract the mean. Compute each deviation xᵢ − mean.
- Square the deviations. Calculate each (xᵢ − mean)².
- Add those squares. This gives the sum of squared deviations.
- Divide for variance. Use N for a population or n − 1 for the usual sample variance.
- Take the square root. The result is standard deviation in the original units.
Carry full precision through intermediate calculations and round the final answer suitably. Skipping the final square root produces variance, not standard deviation.
Worked Example: Calculate Standard Deviation by Hand
Consider the complete population of eight values 2, 4, 4, 4, 5, 5, 7, 9. The sum is 40 and the population mean is μ = 40 / 8 = 5. Subtract 5 from each value, square each difference, and add the squared differences.
| Value (x) | Deviation (x − 5) | Squared deviation |
|---|---|---|
| 2 | -3 | 9 |
| 4 | -1 | 1 |
| 4 | -1 | 1 |
| 4 | -1 | 1 |
| 5 | 0 | 0 |
| 5 | 0 | 0 |
| 7 | 2 | 4 |
| 9 | 4 | 16 |
The sum of the squared deviations is 9 + 1 + 1 + 1 + 0 + 0 + 4 + 16 = 32. With N = 8, population variance is 32 / 8 = 4. The population standard deviation is √4 = 2.
- 5Mean
- 4Population variance
- 2Population SD
What if the same values are a sample?
Keep the same mean of 5 and squared-deviation sum of 32, but divide by n − 1 = 7. Sample variance is 32 / 7 ≈ 4.5714; sample standard deviation is √(32 / 7) ≈ 2.1381. The different answer follows from the interpretation of the data—not from a calculation error.
Same Mean, Different Standard Deviations
To compare like with like, treat each five-value dataset as a complete population. Both datasets below have mean 50, but their spreads are very different:
| Dataset | Values | Mean | Population SD |
|---|---|---|---|
| A — close together | 48, 49, 50, 51, 52 | 50 | √2 ≈ 1.41 |
| B — widely separated | 20, 35, 50, 65, 80 | 50 | √450 ≈ 21.21 |
Dataset A's squared deviations add to 10, giving variance 10 / 5 = 2. Dataset B's squared deviations add to 2,250, giving variance 2,250 / 5 = 450. Identical averages clearly do not guarantee similar values. Standard deviation makes that difference visible.
How to Interpret a High, Low, or Zero Standard Deviation
What does a low standard deviation mean?
A relatively low SD indicates measurements lie closer to their mean. If the same exam is given to comparable classes, a lower SD suggests more similar scores. It does not show whether the average score is high or whether the assessment is valid.
What does a high standard deviation mean?
A relatively high SD indicates observations are more dispersed. A difference of 10 might be large for measurements expected to stay between 0 and 20 but small for prices in the thousands. Always state units, the comparison group, and what practical variation is expected.
Can standard deviation be zero or negative?
If the observations are 7, 7, 7, 7, every deviation is zero and SD is 0. Standard deviation cannot be negative because it is the square root of a nonnegative variance. For the usual sample formula, a single observation has undefined sample SD because n − 1 equals zero.
Units and scaling
If heights are in centimeters, SD is in centimeters; if delivery times are in days, SD is in days. Adding a constant to every value changes the mean but not SD. Multiplying every value by c multiplies SD by |c|: an SD of 0.2 meters equals 20 centimeters.
Standard Deviation vs. Variance
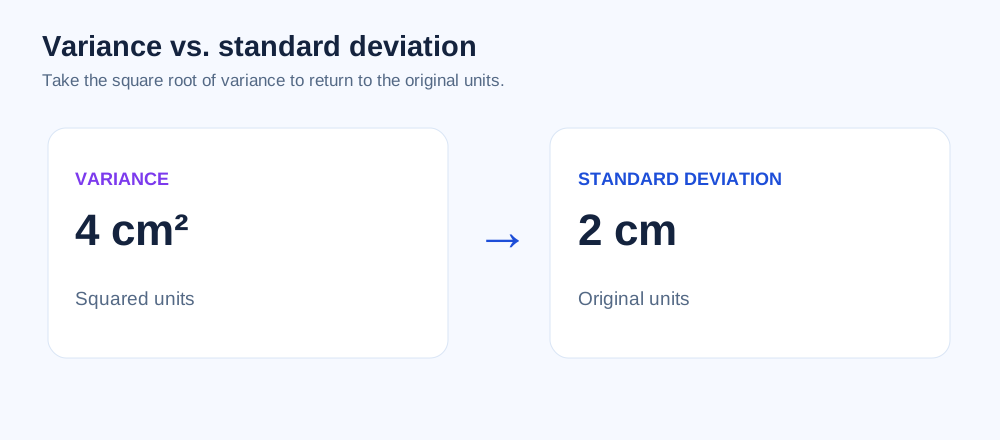
Variance measures the average (or sample-adjusted average) squared deviation. Standard deviation is its square root. They contain the same numerical spread information in different units: if values are measured in centimeters, variance is measured in cm², while SD is in cm.
Variance is useful for statistical theory, estimation, regression and ANOVA. Standard deviation is often easier to explain in a report because the units match the data. Neither measure is universally better.
| Feature | Variance | Standard deviation |
|---|---|---|
| Definition | Combined squared deviation | Square root of variance |
| Population symbol | σ² | σ |
| Sample symbol | s² | s |
| Units | Squared units | Original units |
| Typical role | Model calculations | Describing observed spread |
How Do Outliers Affect Standard Deviation?
SD can rise sharply when a value is much farther from the mean than the others, because differences are squared. For example, consider the full population 10, 11, 12, 13, 14. Its mean is 12 and population SD is √2 ≈ 1.41. Add a genuine observation of 50, and the mean becomes about 18.33 while population SD rises to about 14.22.
That change does not automatically justify removing 50. It could be an entry error, a rare but real event, or the very outcome your investigation should explain. Verify the source and report what happens with and without questionable values when appropriate. A fixed “more than 2 SD” rule cannot identify outliers reliably across all distributions.
Can You Use Standard Deviation for Skewed Data?
Yes. SD is mathematically defined for skewed numerical data with finite variance. But when a few high values dominate a right-skewed distribution, mean and SD alone may give readers an incomplete impression of typical values. In those situations, the median and interquartile range (IQR) often provide a useful complementary, more resistant summary.
A histogram helps reveal skew, peaks and tails; a box plot can show median, quartiles and potential extreme observations. The presence of a high SD cannot tell you whether the data are skewed, multimodal or approximately normal: inspect the shape.
Standard Deviation and the 68–95–99.7 Rule
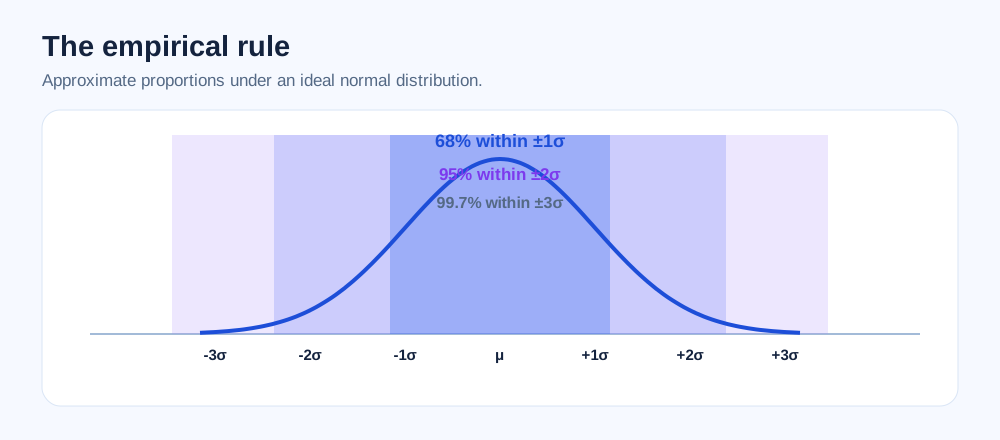
For an ideal normal (bell-shaped) distribution, the empirical rule describes how much probability falls near the mean. About 68% is within one SD, 95% within two, and 99.7% within three.
| Distance from mean | Approximate proportion |
|---|---|
| μ ± 1σ | 68% |
| μ ± 2σ | 95% |
| μ ± 3σ | 99.7% |
For example, with mean 70 and SD 10 under a normal model, about 95% of observations lie between 50 and 90. These figures describe the distribution of individual observations. They are not a 95% confidence interval for the estimated population mean. Nor are they guarantees for skewed, heavy-tailed or multimodal datasets.
Standard Deviation vs. Standard Error
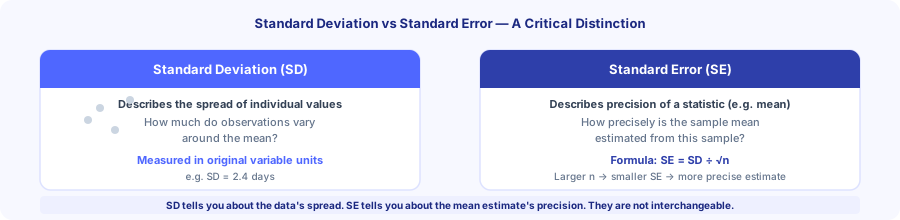
Standard deviation (SD) describes spread among the observations. Standard error (SE) describes sampling variation in an estimated statistic across repeated samples. For the sample mean under usual independent-sampling conditions, the estimated standard error is SE(x̄) = s / √n.
For example, with sample SD 12 and n = 36, estimated SE of the mean is 12 / √36 = 2. The observations still have estimated SD 12, but the sample mean has an estimated SE of 2. Other estimators require other SE formulas. An interval like “mean ± 2 SD” is not automatically a confidence interval for a population mean.
| Feature | Standard deviation | Standard error |
|---|---|---|
| Describes | Variability of observations | Sampling variability of an estimate |
| Example symbol | s | SE(x̄) |
| Typical interpretation | How spread out are the values? | How precise is the estimated mean? |
| Usual mean formula | s | s / √n (independent sampling) |
Standard Deviation vs. Range and Interquartile Range
Range equals maximum minus minimum and is simple but depends on just two observations. IQR equals the 75th percentile minus the 25th percentile and summarizes the spread of the middle half, resisting extremes more than SD. SD uses all numerical values, measuring dispersion around the mean.
| Measure | What it summarizes | Common companion |
|---|---|---|
| Range | Distance between minimum and maximum | Basic summaries |
| IQR | Spread of middle 50% | Median |
| Variance | Squared deviations | Statistical models |
| Standard deviation | Spread around mean | Mean |
No pairing is mandatory in every report. Choose the summary that matches the analytical question and distribution. A small box-plot or histogram can make the choice easier to explain.
Standard Deviation and Z-Scores
A z-score expresses a value's distance from the population mean in SD units: z = (x − μ) / σ, for σ > 0. If μ = 70, σ = 10 and an observed score is 90, the z-score is (90 − 70) / 10 = 2: two population standard deviations above the mean.
You do not need a normal distribution merely to calculate a z-score. However, assigning a normal percentile or probability requires a defensible distributional assumption. In descriptive sample calculations, values may instead be standardized using x̄ and s.
Coefficient of Variation and Scale
When comparing relative variability for positive, ratio-scale data, the coefficient of variation (CV) can help: CV = (s / x̄) × 100% for a sample with a meaningful, nonzero positive mean. For example, SD 5 and mean 50 give CV 10%.
CV can mislead when the mean is near zero or negative, or when the scale has an arbitrary zero, such as temperatures in Celsius. It should not be used as a universal comparison across unrelated measurements.
Real-World Uses of Standard Deviation
- Education: Compare how dispersed scores are, without confusing consistency with achievement.
- Manufacturing: Monitor variation in product dimensions, alongside specifications and process stability.
- Operations: Describe how delivery or response times vary around an average.
- Research: Report spread in observed measurements and distinguish SD from the uncertainty of sample estimates.
- Finance: Summarize historical return volatility; remember that SD does not capture every type of risk or guarantee future outcomes.
- Personal datasets: Assess variation in monthly spending or training measurements after checking for data gaps.
Standard deviation is one of several descriptive statistics used in data analysis. It answers a specific question about spread, not every question about how a dataset behaves.
How to Calculate Standard Deviation in Software
Software makes the arithmetic fast, but you must choose the right definition. In Excel, STDEV.S estimates SD from sample observations, while STDEV.P treats the supplied values as the full population. In Python's standard-library statistics module, stdev and pstdev make a similar distinction.
NumPy's std uses ddof=0 by default, which divides by N; specify ddof=1 to obtain the usual sample SD in typical one-dimensional, unweighted settings. Always check missing-value treatment and the tool's documentation before comparing results from different products.
For an uploaded dataset, examine the histogram first when interpreting spread, and confirm whether any automatically reported SD is labeled as sample or population. Do not assume that every AmriData feature or tool reports both definitions without checking the live feature.
Common Standard Deviation Mistakes
- Calling SD the average absolute distance. SD uses squared deviations and a square root, unlike mean absolute deviation.
- Choosing n or n − 1 without a reason. Decide whether observations represent a population or sample for your purpose.
- Forgetting the final square root. That leaves variance, with squared units.
- Assuming low SD is good. Interpret relative to the domain and objective.
- Using the empirical rule for every dataset. Its familiar percentages rely on an approximately normal shape.
- Confusing SD and SE. One concerns observations; the other concerns variability of an estimate.
- Automatically deleting extreme values. Investigate whether they are real or erroneous.
- Inferring outliers or normality from SD alone. SD does not reveal the full distribution shape.
Practice Problems With Worked Answers
1. Find the population SD of 2, 4, 6, 8.
Mean = (2 + 4 + 6 + 8) / 4 = 5. Deviations: −3, −1, 1, 3; squares: 9, 1, 1, 9, totaling 20. Population variance = 20 / 4 = 5. Population SD = √5 ≈ 2.236.
2. Treat the same four values as a sample.
The squared deviations still total 20. Sample variance = 20 / (4 − 1) = 20 / 3 ≈ 6.667. Sample SD = √(20 / 3) ≈ 2.582. The denominator changed because the interpretation changed.
3. Which of two classes has greater spread?
Class A: 48, 49, 50, 51, 52. Class B: 20, 35, 50, 65, 80. Both average 50, but Class B has larger SD because its observations lie farther from 50. As populations: A ≈ 1.41; B ≈ 21.21.
4. What is SD if every value equals 7?
All deviations equal zero, so SD = 0 (for the four-value population or four-value sample).
5. Find a z-score if μ = 100, σ = 15 and x = 130.
z = (130 − 100) / 15 = 2. The value is two SDs above the population mean; this does not by itself determine its percentile.
6. Can the empirical rule be applied automatically to skewed data?
No. The 68–95–99.7 percentages describe an approximately normal distribution. Strongly skewed data can have very different proportions inside these intervals.
Frequently Asked Questions About Standard Deviation
What is standard deviation in simple terms?
Standard deviation summarizes how widely numerical values vary around their mean. A relatively small SD means values cluster more closely; a larger one means they spread farther apart.
What is the formula for population standard deviation?
Population SD is σ = √[Σ(xᵢ − μ)² / N]. Subtract the population mean from each value, square and sum the deviations, divide by the population size, then take the square root.
How do I calculate sample standard deviation?
Calculate sample mean x̄, sum squared deviations Σ(xᵢ − x̄)², divide by n − 1, then take the square root. The usual sample SD requires at least two values.
Why is n − 1 used for a sample?
Using the sample mean from the same observations reduces the number of independent deviations by one. Dividing the squared-deviation total by n − 1 corrects the usual estimator of population variance under ordinary random-sampling assumptions.
Is a high standard deviation good or bad?
Neither by itself. High SD means more spread on that scale; whether this is desirable depends on the question, units, and real-world context.
Can standard deviation be negative?
No. Squared deviations are nonnegative, so variance and its square root cannot be negative. Standard deviation can equal zero if all values are identical.
What is the difference between variance and standard deviation?
Variance combines squared deviations and has squared units. Standard deviation is its square root, so it has the same units as the original observations.
What is the difference between standard deviation and standard error?
Standard deviation describes variation among measured observations. Standard error describes how an estimated statistic would vary across repeated samples; the usual estimated SE of a sample mean is s / √n.
Does standard deviation require a normal distribution?
No. It can be calculated for numerical datasets without normality. The special 68–95–99.7 interpretation is appropriate for a normal or approximately normal distribution.
How do outliers affect standard deviation?
Large deviations are squared, so genuine extreme values can substantially increase SD. Investigate unusual observations rather than automatically excluding them.
Is the empirical rule a confidence interval?
No. Mean ± 2 population SD describes an interval containing roughly 95% of individual observations in a normal model; a confidence interval for the population mean uses standard error and an appropriate critical value.
What units does standard deviation have?
The same units as the original data: seconds for times, dollars for costs, or centimeters for lengths. Variance instead uses squared units.
When should I report median and IQR instead?
Median and IQR can be helpful for strongly skewed or outlier-prone data because they are less sensitive to extreme values. Consider your analytical goal and show a plot where possible.
How is standard deviation used in a z-score?
A z-score divides the difference between a value and mean by SD. For example, x = 90, mean = 70, and SD = 10 produce z = 2.
Key Takeaways
- Mean describes center; standard deviation describes spread. Use both where appropriate.
- Population SD divides by N; usual sample SD divides by n − 1.
- SD is based on squared deviations and uses the original observation units.
- SD can be calculated for skewed data, but a plot plus median/IQR may describe the shape more helpfully.
- The 68–95–99.7 rule requires an approximately normal distribution.
- SD and standard error are not interchangeable; their questions and formulas differ.
Bottom line: Standard deviation measures how dispersed numerical observations are around their mean. The useful part is not only calculating it, but choosing the correct formula and interpreting the spread in context.
Further Reading and Statistical Sources
- OpenStax — Measures of the Spread of the Data: population and sample formulas and worked examples.
- Khan Academy — Population and Sample SD Review: intuitive calculation steps.
- OpenStax — The Standard Normal Distribution: empirical rule and z-scores.
- NIST/SEMATECH — Statistics Glossary: variance, SD and standard error definitions.
- Microsoft Support — STDEV.S: sample formula.
- NumPy — std: degrees-of-freedom parameter.